
Automate Files, Content, Links and Archives
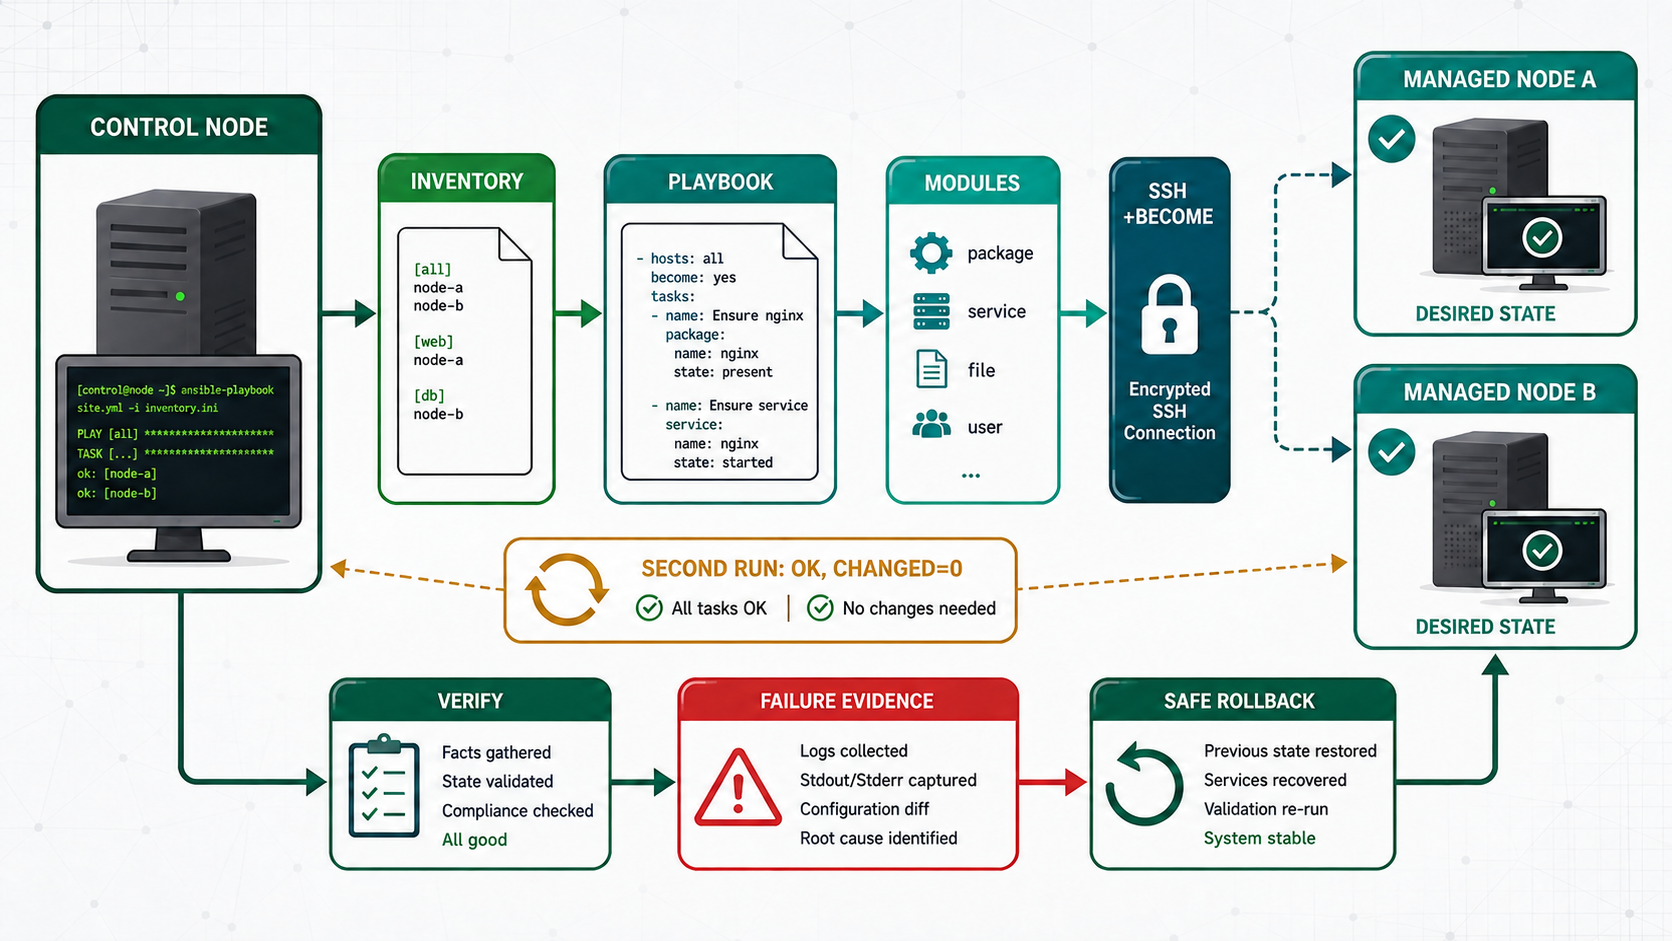
Ansible has distinct modules for metadata, managed content, bounded edits, transfer and archives; choosing the wrong one can overwrite ownership or duplicate text. The useful question is not whether the playbook finished; it is whether another operator can explain the selected hosts, inputs, module decisions, changes, failures and rollback from retained evidence.
Inherited lab checkpoint and starting evidence
Begin with the accepted checkpoint from the preceding lesson. Confirm both managed nodes answer the inventory and preserve the current project commit before changing this layer.
pwd
ansible --version
ansible-config dump --only-changed
ansible-inventory --graph
git status --short
Capture this output before changing the file and archive state. Keep host keys, vault passwords, private keys and tokens out of terminal transcripts and Git. The examples use control.example.test, nodea.example.test and nodeb.example.test; replace them only with identities verified in your own inventory.
Understand the file and archive state
| Question | Operator decision | Evidence |
|---|---|---|
| Scope | Which hosts and groups should receive the change? | Inventory graph and explicit limit |
| Input | Where does each value originate? | Variable inspection without secret disclosure |
| State | Which module expresses the required result? | Module documentation and diff |
| Failure | What must stop, continue or recover? | Recap, registered result and managed-node logs |
| Persistence | Does the result survive service restart or reboot? | Second run and client-side acceptance |
Prepare the project safely
cd ~/ansible-lab
git status --short
ansible-inventory -i inventories/lab.ini --graph
ansible all -i inventories/lab.ini -m ansible.builtin.ping --limit nodea.example.test
Work in a dedicated Git repository, inspect configuration precedence and commit no generated secrets. Use a named inventory and an explicit limit until host selection is proven.
Build the complete working example
---
- name: Create application directory
  ansible.builtin.file:
    path: /srv/app/releases
    state: directory
    owner: app
    group: app
    mode: '0750'
- name: Install managed notice
  ansible.builtin.copy:
    content: |
      Managed by Ansible. Local edits will be replaced.
    dest: /etc/app/NOTICE
    owner: root
    group: root
    mode: '0644'
    backup: true
Quote permission modes so YAML does not reinterpret them. The directory and file have separate contracts; backup creates a remote copy but does not replace version control or system backup.
Run, inspect and repeat
ansible-playbook --syntax-check -i inventories/lab.ini playbooks/site.yml
ansible-playbook --check --diff -i inventories/lab.ini playbooks/site.yml
ansible-playbook -i inventories/lab.ini playbooks/site.yml
ansible-playbook -i inventories/lab.ini playbooks/site.yml
The first run may report a controlled change. The second run should normally report changed=0 for the same desired state. If it changes again, identify the non-idempotent task rather than accepting noisy automation as normal.
Interpret the execution result
| Signal | Healthy meaning | What a different result means |
|---|---|---|
| ok | Task inspected state and required no change | Confirm this was the intended host and state |
| changed | Module made a declared change | Review diff and handler notification |
| failed | Task could not establish its contract | Read module message and managed-node evidence |
| unreachable | Connection or transport failed before task execution | Check inventory, SSH, host key, route and Python |
| rescued or ignored | Play continued under explicit failure policy | Ensure the exception is visible and owned |
Read the recap as a starting point, not as the acceptance test. A green play can still select the wrong host, install an unintended version, expose a service on the wrong interface or leave a change that disappears after reboot. Tie each requirement to evidence from the managed node and, where practical, to a client-side test. Keep the command, relevant output, inventory limit and Git revision together so another administrator can reproduce the decision.
When a run fails, resist changing several layers at once. First confirm inventory selection and transport, then privilege, input data, module arguments, managed-node state and finally the application response. Make one attributable correction and rerun the smallest safe scope. This preserves the causal evidence that disappears when shell commands, manual edits and repeated full-fleet runs are mixed together.
Practical use cases
| Use case | Implementation choice | Acceptance |
|---|---|---|
| Single setting | Use lineinfile with a unique regexp and validation | Exactly one intended line exists |
| Owned block | Use blockinfile with stable markers | The block updates without duplication |
| Narrow rollout | Use --limit and serial execution before the complete group | Only intended hosts change and availability remains inside its budget |
| Dependency outage | Stop the named lab dependency and retain the failed result | Failure is visible, bounded and recoverable without manual drift |
A recursive mode change removes directory traversal
One file task recursively applies mode 0640 to an application tree, making directories non-traversable. Separating directory and file predicates, previewing the target and restoring from a metadata manifest prevents a broad permission outage.
Troubleshoot by symptom
| Symptom | Inspect first | Correction |
|---|---|---|
| Content duplicates | Regexp or block markers | Use a unique stable ownership boundary |
| Permission appears correct but access fails | Parent traversal, ACL, SELinux and mount | Correct the actual denying layer |
| Host is unreachable | Inventory variables, DNS, SSH host key and Python | Repair connection ownership before changing the play |
| Second run changes again | Diff, volatile input and task semantics | Replace imperative work with a stable desired-state test |
Unsafe shortcuts and recovery boundaries
- Unsafe: recursive ownership or mode at a broad unresolved path can disable the system.
- Unsafe: unarchive on an untrusted archive can write unexpected paths.
- Unsafe: synchronize with delete can remove remote files outside the intended source truth.
Production operation and rollback
Store the reviewed project in Git, pin external content, separate inventory data from secrets and promote the same commit through environments. Monitor unreachable, failed, rescued, ignored and changed results separately.
ansible-playbook --syntax-check -i inventories/lab.ini playbooks/rollback.yml
ansible-playbook --check --diff --limit nodea.example.test -i inventories/lab.ini playbooks/rollback.yml
ansible-playbook --limit nodea.example.test -i inventories/lab.ini playbooks/rollback.yml
Rollback is an automation path with its own test, not a promise to edit hosts manually after failure. Preserve the previous artifact, limit the host pattern, execute serially where availability requires it and verify the restored service from the client side.
Knowledge checks with explained answers
Guided lab and independent challenge
- Recreate the starting state on nodea and nodeb and record the inventory graph.
- Run syntax and check mode against nodea only; explain every predicted change.
- Run the play against both nodes and verify the result from the service or client side.
- Run it again and investigate any unexplained change.
- Inject the lesson-specific failure, capture the failed layer and execute the reviewed recovery.
- Complete the same end state from a fresh Git checkout without copying commands from the article.
Repeat the challenge against fresh nodes. The completed state, not a remembered command sequence, is the assessment target. Save syntax output, first and second recaps, a negative test and the rollback result.