
AWS 091: Placement groups
The real problem
A team recognizes the name Placement groups but has not connected the feature to a real requirement, identity boundary, network or data path, failure mode, price dimension, and cleanup owner. A plausible configuration could still fail the workload.
Final outcome
The learner will produce a requirement-led artifact for Placement groups, inspect the matching AWS control plane in the Management Console, run a matching CloudShell or AWS CLI query, interpret the output, diagnose one failure, defend one architecture choice, and prove cleanup or approved retained state.
The practical outcome is not a command transcript. It must show what was expected, what happened, what the result proves, what it does not prove, and which evidence would change the decision.
Learning objectives
By the end of this lesson, the learner can:
- explain a placement group influences instance placement;
- explain cluster minimizes network distance;
- explain partition separates hardware groups;
- explain spread isolates a small set of instances;
- explain placement can fail for capacity;
- connect control-plane state to the real data, network, identity, or application behavior;
- identify cost and cleanup ownership before any optional mutation;
- troubleshoot from evidence without opening broad access or adding broad permissions.
Relationship model
Requirement
   |
   v
Identity and policy -> AWS configuration -> network or data path -> workload behavior
        |                    |                      |                    |
        +--------------------+----------------------+--------------------+
                                      |
                                      v
                         monitoring, cost, recovery, cleanup
Use this model to separate an AWS object that exists from a result that actually works. Every arrow is a verification boundary.
Prerequisites, permissions, Region, and safety
- Learning baseline: This sequence assumes practical Linux knowledge but no prior cloud-computing or AWS knowledge. Cloud, networking, security, data, automation, and architecture concepts must come from completed earlier lessons. If a prerequisite checkpoint is incomplete, return to its linked lesson before continuing.
- Confirm a non-root caller with
aws sts get-caller-identityand keep the account number private. - Use
ap-south-1unless this lesson explicitly names a second Region. - Confirm the intended profile and Region with
aws configure listbefore interpreting an empty result. - Use read-only List, Get, and Describe permissions for the named services. Design exercises run locally and require no resource-creation permission.
- This is a no-create lesson. Console and CLI work is read-only, and every design artifact is created locally.
- Never publish account IDs, public addresses, ARNs containing private account data, session IDs, presigned URLs, object data, credentials, or KMS material.
- Do not use root, world-open SSH or RDP, disabled TLS verification, unowned resources, or irreversible retention controls in a training exercise.
Core model
| Concept | What the learner must understand |
|---|---|
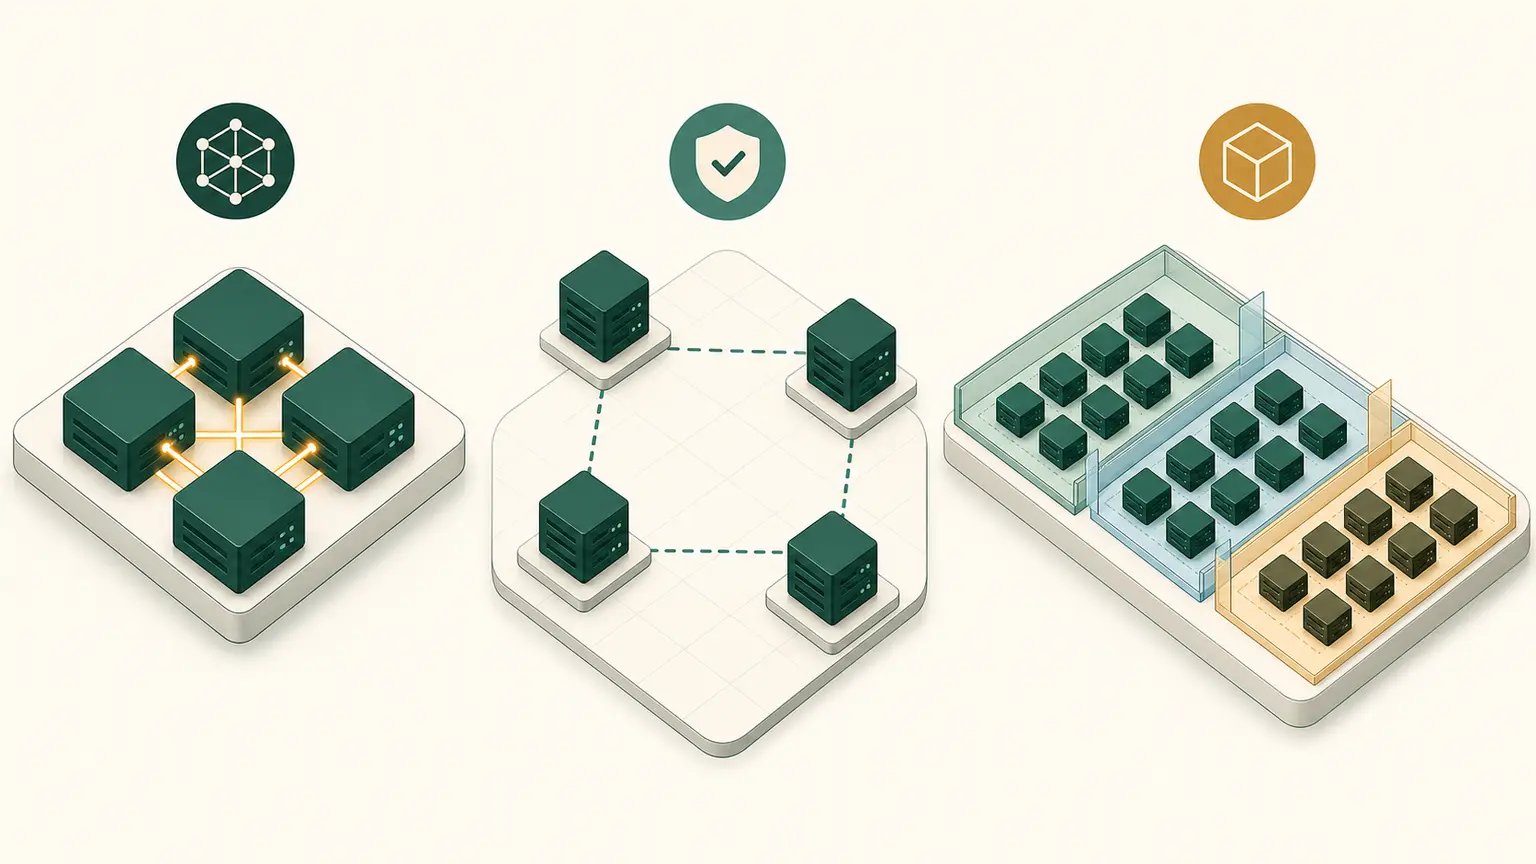
| A placement group influences instance placement | Cluster, partition, and spread strategies request different relationships among EC2 instances. They do not replace Multi-AZ application and data resilience. |
| Cluster minimizes network distance | Instances are packed close together in one Availability Zone for low latency and high network throughput. The placement also creates a correlated failure risk. |
| Partition separates hardware groups | Instances in one partition do not share the same underlying racks with instances in another partition. The application can map replicas across partitions. |
| Spread isolates a small set of instances | Each spread instance is placed on distinct hardware. Spread groups have a limit of seven running instances per Availability Zone for the common rack-level design. |
| Placement can fail for capacity | Launching all members together and using compatible, similar instance types can improve success. Stop and start all members may allow regrouping after an insufficient-capacity event. |
| Rules and limits vary by strategy | AZ span, tenancy, supported instance types, network behavior, and maximum partitions differ. Confirm current documentation for the exact design. |
How it works
Use a placement group only when the application understands the failure and performance tradeoff. Cluster favors performance, partition favors topology-aware distributed systems, and spread favors a small number of individually critical instances.
Read the result in layers:
- Scope: account, Region, VPC, bucket, AZ, endpoint, principal, object version, or resource ARN.
- Control plane: the requested configuration exists and reached an expected state.
- Behavior: the request, connection, health check, replication, restore, or application result meets the requirement.
- Operations: monitoring, failure owner, cost, retention, rollback, and cleanup are known.
Control-plane success is necessary but not sufficient. A resource can be available while policy, routing, DNS, health, data, or application behavior remains wrong.
Architecture decision table
| Requirement | Preferred direction | Why |
|---|---|---|
| Tightly coupled HPC nodes need lowest latency | Cluster placement group | Close placement supports high packet rate and network throughput. |
| Large distributed database maps replicas to failure groups | Partition placement group | The application can place replicas in separate hardware partitions. |
| Three critical peer instances need hardware separation | Spread placement group | Each instance uses distinct underlying hardware. |
| Web tier needs ordinary Multi-AZ scaling | Auto Scaling across subnets without placement group | Independent replaceable nodes need zonal distribution more than special co-location. |
Professional questions normally contain several valid services. State the requirement that selects one option, why the nearest alternative fails it, and what changed requirement would reverse the choice.
AWS Management Console guided practice
Before opening a service page, write the expected account, Region, starting state, and evidence. Do not choose Create, Save, Purchase, Lock, or Delete unless the lesson explicitly authorizes the live track.
- Open EC2 Placement Groups and inspect the Strategy and partition count of an existing group.
- Create a draft learning design for cluster, partition, or spread and compare its displayed restrictions before creating resources.
- Open Instances and add Placement group and Partition number columns to verify actual membership and topology.
For each step, capture the field name and value in text. A screenshot may support the record but does not replace the explanation. Console labels can evolve, so use the service search and current documentation if a navigation label differs.
CloudShell and AWS CLI practice
CloudShell is the default browser-based command environment taught in AWS 028. AWS 029 and AWS 030 cover local CLI installation and authentication. This lesson therefore does not assume that an unconfigured local shell is ready.
Start every session with:
export AWS_DEFAULT_REGION="ap-south-1"
aws sts get-caller-identity --query Arn --output text
aws configure list
Redact the account portion of the ARN before sharing. Then perform the topic query:
Read strategy, partition count, and instance membership.
aws ec2 describe-placement-groups --group-names ExampleGroup
aws ec2 describe-instances --filters Name=placement-group-name,Values=ExampleGroup --query 'Reservations[].Instances[].{Instance:InstanceId,AZ:Placement.AvailabilityZone,Partition:Placement.PartitionNumber,State:State.Name}' --output table
Expected interpretation:
Membership does not prove the application has correct replica placement. Compare partitions and AZs with application topology.
Replace every replace-with-... sample value before running its command, and use only an explicitly owned resource. Explain each option first. These queries are read-only; a successful response does not authorize a later create or delete operation.
Practical work
Create p05-placement-decision.md. Evaluate cluster, partition, and spread placement groups for a tightly coupled HPC job, distributed partition-aware system, and small critical replica set. Record supported instance and AZ constraints, network behavior, maximum failure boundary, launch capacity risk, scaling interaction, and why the ordinary P05 web tier uses no placement group.
The evidence package must contain:
- the problem and final requirement in the learner's own words;
- caller type and Region with private identifiers redacted;
- exact planned values, ownership, and cost class;
- one Console observation and matching CLI or API evidence;
- one behavior result or supplied data-plane record;
- one denied, failed, or counterexample result and evidence-led diagnosis;
- one architecture choice plus the rejected alternative;
- cleanup proof or explicit retained-state owner, expiry, and next lesson.
Verification standard
Use expected state before observed state. Record timestamps in UTC and preserve the original failure before changing anything. A passing submission answers all four questions:
- What exact requirement was tested?
- Which evidence proves the AWS configuration?
- Which evidence proves the workload behavior?
- What remains unproven or requires later monitoring?
If AWS returns no rows, verify account, Region, permission, filters, pagination, resource type, and deletion state before concluding that nothing exists.
Common failures and troubleshooting
| Symptom | Evidence first | Likely boundary | Smallest safe response |
|---|---|---|---|
| object appears missing | caller, Region, filters, pagination, tags | scope or read permission | align scope before creating a duplicate |
| state remains pending or unavailable | service state, events, dependencies, quotas | dependency or capacity | correct the named dependency and wait with a bound |
| AccessDenied | principal, action, resource, explicit-deny context | identity, resource, endpoint, organization, or KMS policy | change only the proven policy layer |
| configuration exists but behavior fails | route, DNS, security, listener, health, logs, object version | data path or application | test the next boundary and change one control |
| bill is higher than expected | hours, bytes, requests, AZs, addresses, retention | cost model or retained resource | stop optional work and reconcile the ledger |
| cleanup is blocked | dependency inventory and owning service | deletion order or immutable state | remove owned dependants in reviewed reverse order |
Do not troubleshoot by attaching administrator access, opening administration ports to the internet, disabling encryption, retrying uncontrolled creation, deleting unknown resources, or weakening retention.
Cost, cleanup, and retained state
No AWS resource is created. Close CloudShell and remove or redact downloaded evidence.
Cleanup evidence requires terminal state and an after-inventory. Search related ENIs, public IPv4 addresses, EBS volumes and snapshots, load balancers, target groups, Auto Scaling instances, endpoints, logs, S3 versions and delete markers, backup recovery points, and global IAM roles when they apply. Billing data can lag, so schedule a later review.
Architecture and certification decisions
- Certification coverage: SAA-C03; SOA-C03; SAP-C02; DOP-C02.
- Exam mapping: SAA D2-D4.
- Explain service scope, failure boundary, consistency, recovery, security, operations, and price rather than matching a keyword.
- Treat availability and durability, encryption and authorization, routing and filtering, health and lifecycle, backup and replication, and discount and capacity as separate concepts.
- Do not reproduce protected certification questions.
Knowledge check
- Which strategy is best for tightly coupled low-latency compute?
Expected direction: Cluster.
- Which strategy exposes partitions to topology-aware software?
Expected direction: Partition.
- What is the common spread limit per AZ?
Expected direction: Seven running instances per Availability Zone for a spread placement group.
- Does a cluster placement group improve AZ fault isolation?
Expected direction: No. It is in one AZ and trades broader isolation for close placement.
Completion gate and assessment
| Area | Points | Passing evidence |
|---|---|---|
| Requirement and model | 15 | Correct scope, terminology, and final outcome |
| Console evidence | 15 | Current path and interpreted fields |
| CLI or API evidence | 15 | Scoped command, expected result, and limitations |
| Behavior or decision exercise | 20 | Reproducible result or defensible architecture reasoning |
| Troubleshooting | 15 | Original symptom, hypothesis, one change, retest, rollback |
| Security and cost | 10 | Least privilege, data protection, current price dimensions |
| Cleanup and handoff | 10 | Terminal-state proof or approved retained-state record |
Pass at 80 out of 100 with no critical safety failure. A missing practical artifact, unexplained output, unsafe access, destructive action outside the owned scope, unplanned billed resource, or false cleanup claim requires remediation and a changed retest.