
AWS 020: Relational, key-value, document, graph, cache, and analytics data models
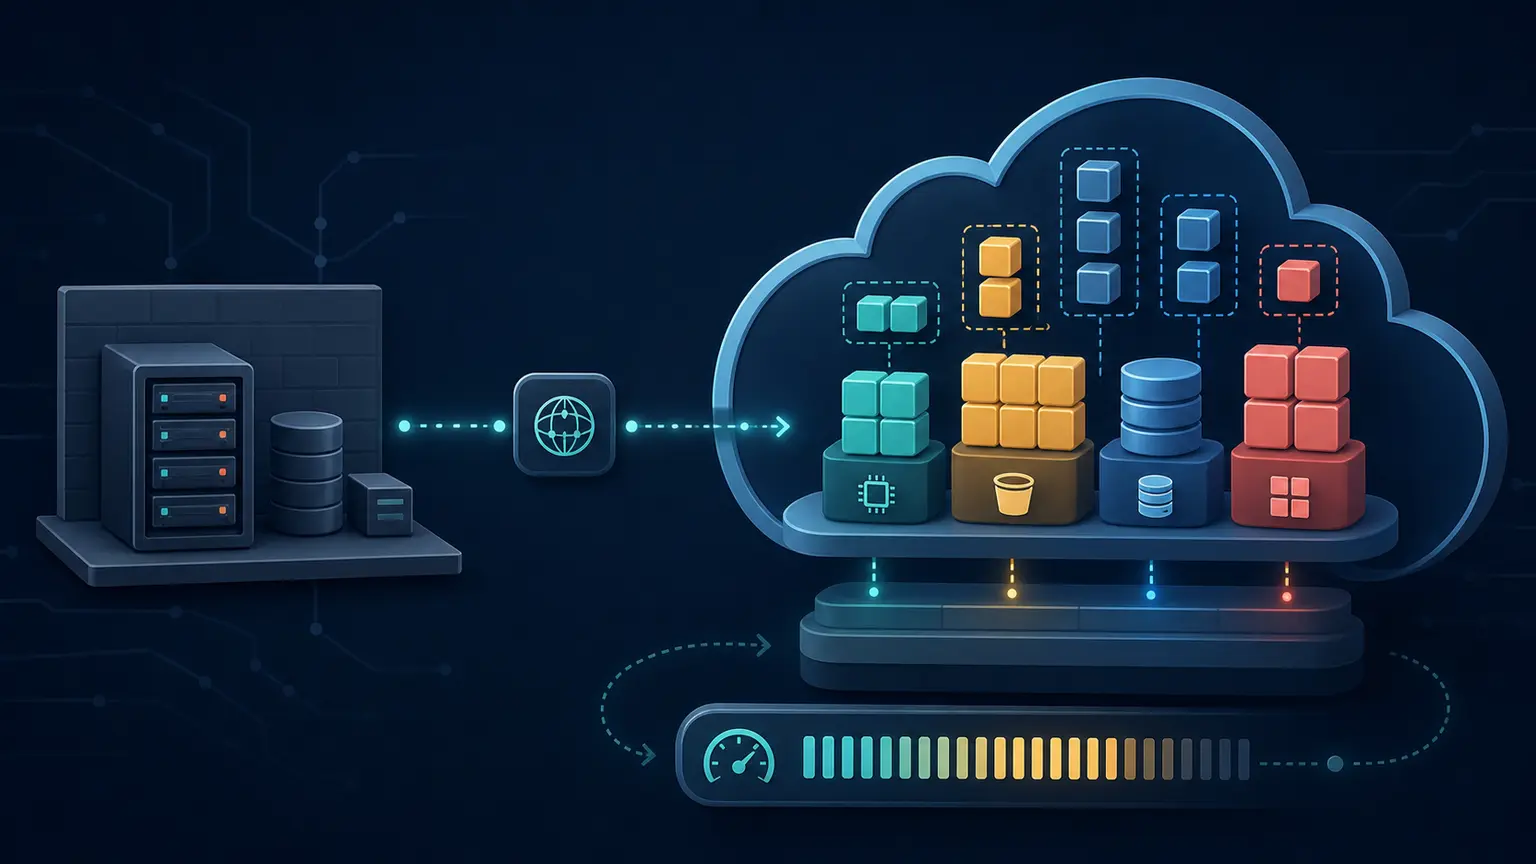
The problem
A team selects a database because it is fashionable, then tries to force transactions, relationship traversal, session caching, full-text search, and analytics into one model.
Start with data shape, access patterns, consistency, scale, latency, recovery, and operations.
Learning outcomes
You will be able to distinguish major data models, match access patterns to a model, explain why a cache is not automatically a durable source of truth, and document a purpose-built data decision.
Relational
Relational databases organize data into tables with defined relationships and support queries and transactions.
Good fit:
- orders, payments, inventory, and records with relational integrity;
- multi-row transactional requirements;
- flexible SQL queries and joins;
- established relational tooling.
AWS options include Amazon RDS and Amazon Aurora engines. Engine behavior and features differ.
Key-value
A key-value database retrieves a value from a unique key.
Good fit:
- high-scale predictable access by key;
- sessions, carts, profiles, state, and metadata designed around known access patterns;
- simple low-latency operations.
Amazon DynamoDB supports key-value and document data patterns. Good key design is central. Do not expect arbitrary relational joins.
Document
Document stores keep JSON-like records with nested fields and flexible structure.
Good fit:
- content catalogs;
- profiles with varying attributes;
- applications naturally using document objects.
Flexible schema does not mean no schema. Applications still need validation, versioning, indexing, and migration rules.
Graph
Graph databases model vertices and relationships for traversal.
Good fit:
- fraud relationships;
- social connections;
- network topology;
- recommendation paths;
- knowledge graphs.
Amazon Neptune provides graph database capabilities. A graph is selected because relationship traversal is central, not because every dataset has relationships.
Cache and in-memory data
A cache stores data for faster access and commonly has a defined eviction and expiration policy.
Good fit:
- repeated expensive reads;
- sessions where the chosen service's durability matches requirements;
- computed results;
- rate limits and transient state.
AWS explicitly distinguishes ephemeral caching such as ElastiCache from durable in-memory database use cases such as MemoryDB.
If cache loss breaks correctness or destroys the only copy, it was being used as a primary store and must be designed accordingly.
Analytics
Analytics systems optimize scanning, aggregating, and analysing large data sets rather than serving individual low-latency transactions.
Good fit:
- reports across long periods;
- business intelligence;
- data warehouse queries;
- lake analytics;
- historical trends.
Operational transaction processing and analytical processing have different access and performance patterns. Replicate or transform data deliberately rather than running unbounded analytics against the production transaction path.
Purpose-built does not mean uncontrolled sprawl
Using several stores can improve fit but adds:
- data movement;
- consistency;
- backup and recovery;
- security policy;
- observability;
- skills;
- cost;
- ownership;
- deletion and retention coordination.
Use the fewest models that satisfy the actual requirements.
Access-pattern-first exercise
Create:
mkdir -p "$HOME/nitwings-aws/evidence/aws-020"Create data-model-decisions.md for the training portal.
| Data and access | Candidate model | Reason |
|---|---|---|
| Assessment submission with learner, exam, answer, timestamp, and transaction rules | ||
| Retrieve learner session by opaque session ID | ||
| Lesson document with variable content blocks | ||
| Find paths between accounts, devices, IPs, and suspicious transactions | ||
| Cache the most-read course catalog for five minutes | ||
| Report completion rate by course and month across years |
Expected directions:
- relational can fit transactionally related assessment records;
- key-value can fit direct session lookup;
- document can fit variable lesson content;
- graph can fit relationship traversal;
- cache is a performance layer with expiry and source-of-truth policy;
- analytics store or warehouse fits historical aggregation.
Other answers can pass if access patterns and consequences support them.
Required decision fields
For every row document:
- primary keys or identifiers;
- read and write patterns;
- query flexibility;
- transaction and consistency need;
- expected scale;
- latency;
- retention and deletion;
- backup and RPO/RTO;
- security and data classification;
- source of truth;
- rejected model.
Consistency questions
Ask:
- Must a read immediately observe a completed write?
- Can replicas or caches return older data?
- Can concurrent updates conflict?
- Is a transaction required across records?
- How are retries made idempotent?
- How is the authoritative record identified?
Do not say "NoSQL is eventually consistent" as a universal rule. Consistency capabilities are service and operation specific.
Operational questions
- Who patches the engine or service layer?
- How is capacity managed?
- Which indexes are required?
- How are slow or expensive queries found?
- How are backup and restore tested?
- How is encryption configured?
- How are credentials delivered?
- How is data migrated or exported?
- How is cost measured?
Managed databases reduce infrastructure work, but data modelling and safe operation remain.
Common misconceptions
| Misconception | Correction |
|---|---|
| NoSQL means no structure | Data still has shape, keys, validation, and access patterns |
| One database should hold everything | Different models can serve distinct needs |
| Cache is always disposable | Only if an authoritative source and recovery behavior exist |
| Relational cannot scale | Scaling depends on engine, architecture, workload, and limits |
| Document means no migrations | Applications must evolve document versions |
| Graph is best for any connected data | Use it when traversal is the central access pattern |
| Analytics should query production freely | Isolate analytical load according to requirements |
Knowledge check
- Which model is designed around table relationships and transactions?
- What is the first question before selecting a key-value key?
- When is graph useful?
- Why is a cache not automatically the source of truth?
- Why separate analytical and transactional paths?
Expected answers: relational; access patterns; relationship traversal; eviction or loss may be acceptable and data commonly comes from an authority; workload and performance patterns differ.
Completion gate
Pass when data-model-decisions.md covers all six cases and every decision includes access, consistency, recovery, security, source-of-truth, and rejected-option reasoning.
No AWS resources were created.