Linux Virtual Server High Availability with IPVS and Keepalived
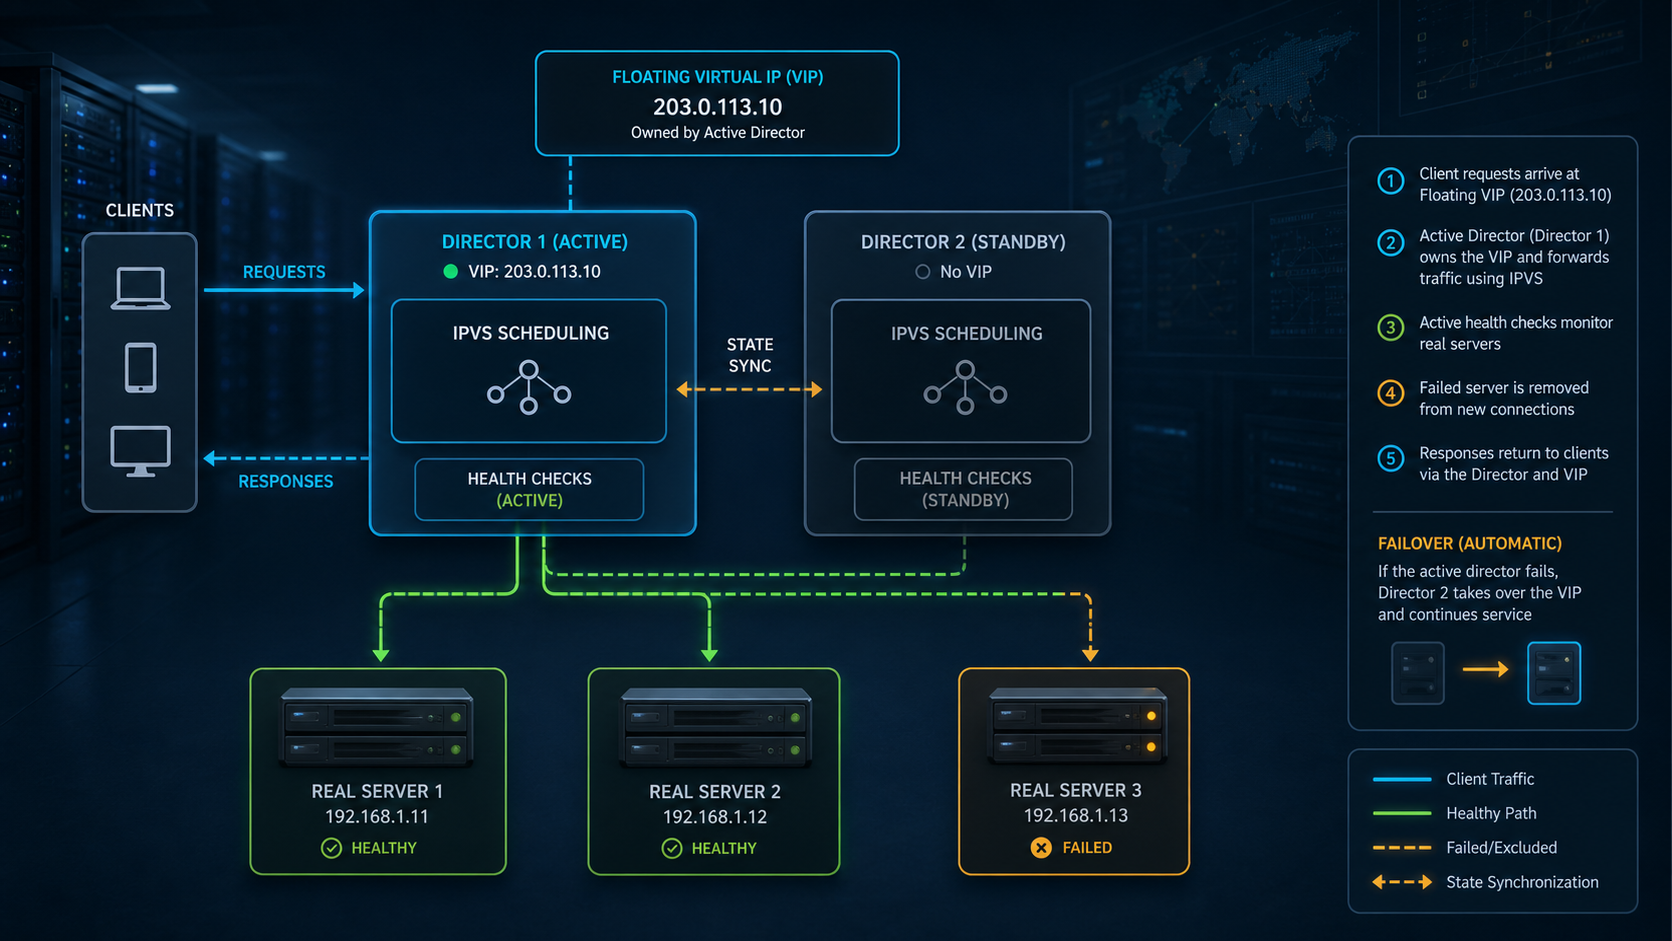
Linux Virtual Server can distribute millions of Layer 4 flows efficiently, but IPVS alone does not create a highly available service. The virtual IP needs one accountable owner, unhealthy real servers must stop receiving new connections, return routing must match the forwarding method, and director failure must be tested without producing two active owners.
This guide builds a two-director LVS service with IPVS and Keepalived, then tests backend failure, director failure, split-brain conditions, connection synchronization, maintenance, and rollback. NAT is the complete step-by-step deployment because it is easiest to reason about across separate frontend and backend networks. Direct Routing and tunneling are covered with their required real-server behavior. A maintained Heartbeat and ldirectord path is included for environments that still operate it.
Understand the four independent functions
| Function | Component | What failure looks like |
|---|---|---|
| Virtual service and packet forwarding | Linux kernel IPVS | The VIP may exist, but no virtual service selects or forwards to real servers. |
| Backend health and IPVS programming | Keepalived checker or ldirectord | A failed application remains eligible, or every backend is removed incorrectly. |
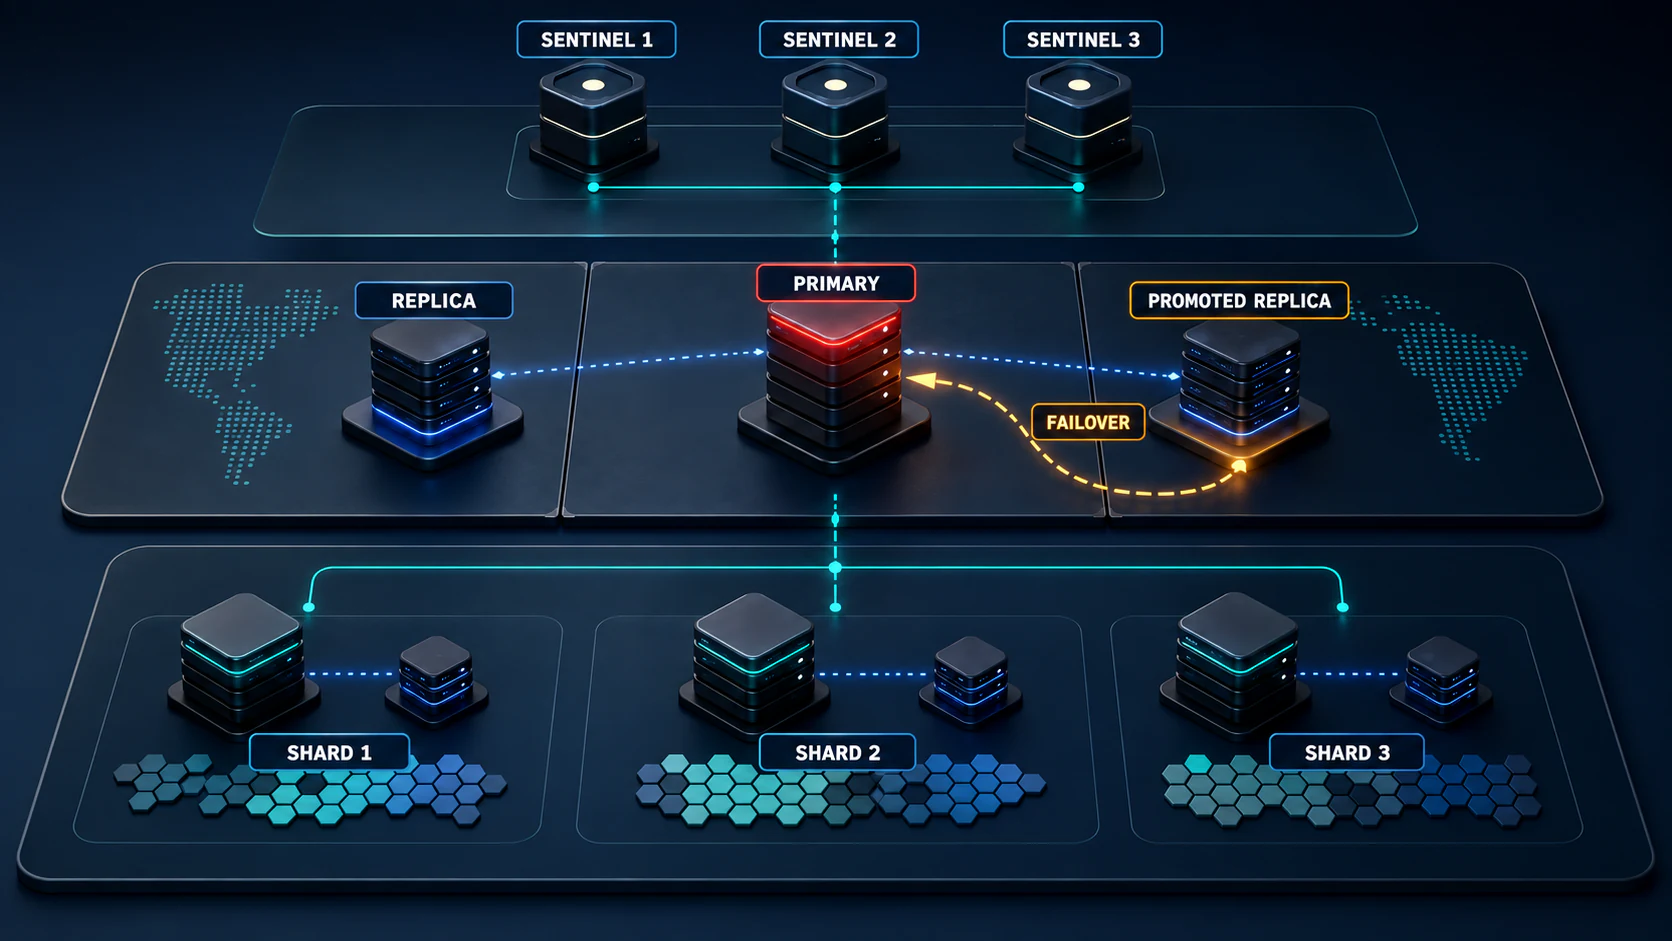
| Director high availability | Keepalived VRRP, or a cluster resource manager | No node owns the VIP, or both nodes believe they own it. |
| Return path | NAT gateway, Direct Routing, or tunnel routing | SYN reaches a real server but the response bypasses the required path or uses the wrong source. |
A heartbeat is only peer-liveness communication. It does not prove that IPVS is configured, the backend route works, the application returns the correct result, the upstream accepts the moved VIP, or an existing connection survived. Test every layer separately.
Choose NAT, Direct Routing, or tunneling deliberately
| Method | Request path | Response path | Real-server requirement | Best fit |
|---|---|---|---|---|
| NAT | Client to director to real server | Real server through active director to client | Return route for client traffic uses the floating backend gateway | Clear isolation and services where director capacity covers both directions |
| Direct Routing | Client to director, then Layer 2 delivery to real server | Real server directly to client | VIP configured locally without answering ARP; real server accepts traffic for VIP | High throughput when directors and real servers share the required Layer 2 domain |
| Tunneling | Client to director, then encapsulated to real server | Real server directly to client | Supported tunnel endpoint, VIP, routing, MTU and source behavior | Geographically or topologically separated real servers |
NAT is not inferior by definition; it has a different capacity and routing model. Direct Routing is not automatically simpler; ARP ownership, asymmetric paths, firewall state, and real-server VIP configuration must be correct. Tunneling adds encapsulation and MTU considerations. Select from measured traffic, topology, operational experience, and failure behavior.
Use a documented NAT topology
| Role | Frontend | Backend | Purpose |
|---|---|---|---|
| Director A | 192.0.2.11/24 on enp1s0 | 198.51.100.11/24 on enp2s0 | Preferred director |
| Director B | 192.0.2.12/24 on enp1s0 | 198.51.100.12/24 on enp2s0 | Standby director |
| Public service VIP | 192.0.2.100/24 | Not applicable | Client destination; owned by one director |
| Backend gateway VIP | Not applicable | 198.51.100.1/24 | Return gateway that moves with the public VIP |
| Real server 1 | None required | 198.51.100.21/24 | Application on TCP 8443 |
| Real server 2 | None required | 198.51.100.22/24 | Application on TCP 8443 |
All addresses use documentation-only networks. Replace them with assigned addresses and confirm that the VIP is unused. Both VIPs must move together. If the public VIP moves but the backend gateway stays on the failed node, new requests may arrive through one director while responses route toward another.
Capacity-plan the directors and network path
IPVS operates at Layer 4. It selects a real server from addresses, ports, protocol, scheduler state, weights, and persistence rules; it does not understand an HTTP URL, tenant, cookie, database query, or application transaction. Keepalived health checks can inspect an application endpoint, but forwarding remains transport-oriented. Decide where TLS terminates, how applications obtain the client address, and which system owns application-level routing before sizing the directors.
| Design input | NAT consequence | DR/TUN consequence | Evidence to collect |
|---|---|---|---|
| Packets and bits per second | Both request and response traverse the director. | Director normally handles the request path; real server handles the direct response. | Peak and percentile packet rate, throughput, packet sizes, and interface drops |
| New connections per second | IPVS and connection tracking/state capacity must cover the full rate. | IPVS still schedules new flows; return traffic consumes less director bandwidth. | SYN rate, completed handshakes, resets, timeout distribution, and connection table growth |
| Long-lived TCP sessions | State remains on the director and failover continuity depends on synchronization. | Director still owns scheduling state even when response traffic is direct. | Concurrent active/inactive connections, age, keepalive behavior, and tested failover loss |
| TLS location | When TLS terminates on real servers, IPVS forwards encrypted TCP without adding HTTP headers. | The same Layer 4 limitation applies. | Certificate ownership, SNI behavior, health-check TLS name, and client-IP requirements |
| Client address | The real server normally sees the original source in LVS-NAT, but the return route must traverse the director. | The real server sees and replies directly to the original client. | Backend packet capture, application logs, proxy layers, and privacy/retention requirements |
| MTU | Ordinary forwarding still needs consistent path MTU and working ICMP handling. | Tunneling adds encapsulation overhead and increases fragmentation/PMTU risk. | Interface MTU, route MTU, encapsulation overhead, retransmits, and large-payload tests |
# Capture capacity evidence on each director during representative load.
ip -s link show dev enp1s0
ip -s link show dev enp2s0
sudo ipvsadm -Ln --stats
sudo ipvsadm -Ln --rate
sudo ss -s
nstat -az | grep -E 'TcpExtListenDrops|TcpExtListenOverflows|IpInDiscards'
cat /proc/sys/net/netfilter/nf_conntrack_count 2>/dev/null
cat /proc/sys/net/netfilter/nf_conntrack_max 2>/dev/null
Do not tune connection-table sizes or IPVS timeouts from a copied “high performance” profile. Larger tables consume memory, longer timeouts retain state, and shorter timeouts can break legitimate idle connections. Measure protocol behavior, calculate headroom for a single surviving director, load test the same kernel/firewall/MTU design, and alert before capacity is exhausted.
Define the security and trust boundaries
The floating VIP is not an authentication control. Protect director management through a separate approved path, restrict VRRP to the peer addresses, restrict synchronization to its dedicated network, and allow real-server health checks only from the directors. Real servers must still authenticate application clients where the protocol requires it. A health endpoint should disclose minimal information and should not become an unauthenticated administrative interface.
Keepalived notification and health scripts run with significant influence over routing. Make every script root-owned, non-writable by service or deployment accounts, absolute-path based, fast, and non-interactive. Never interpolate unchecked network data into a shell command. Protect configuration backups because they can contain peer addresses, notification destinations, database health credentials, and operational topology.
Plan denial-of-service controls outside and inside the directors. IPVS distributes accepted flows; it does not replace upstream capacity protection, SYN defenses, application rate limits, TLS abuse controls, or real-server resource limits. A scheduler can spread overload while every backend still fails. Capacity, admission policy, health behavior, and a deliberate all-backends-down response belong in the same design.
Design IPv4 and IPv6 as separate tested services
Dual-stack DNS does not make an IPv4 LVS configuration serve IPv6. An IPv6 virtual service needs an IPv6 VIP, IPv6-capable real-server addresses or a supported tunneling combination, VRRPv3 behavior, neighbor discovery, router advertisements or static routing, IPv6 firewall policy, IPv6 health-check reachability, and monitoring. The ipvsadm command uses -6 when managing an IPv6 virtual service directly.
Do not publish an AAAA record until the IPv6 path passes the same backend, director, split-brain, MTU, health, failover, and application tests as IPv4. Client fallback can hide a broken IPv6 service during casual testing while users experience long connection delays. Test from IPv6-only and dual-stack clients, and observe the responding address family in application and packet evidence.
Keep the IPv4 and IPv6 service definitions attributable. A shared operational intent is useful, but counters, health, firewall rules, neighbor state, route policy, and failure impact should be visible by address family. Disabling IPv6 on the directors is not a substitute for deciding whether it is supported. Either operate and secure it deliberately or ensure DNS, listening sockets, routing, and policy do not advertise an untested path. Record that decision in the service ownership and recovery runbook.
Record acceptance criteria before installation
- Exactly one director owns both VIPs during healthy operation.
- Both directors have identical IPVS virtual services and backend definitions.
- Only application-healthy real servers receive new connections.
- Removing one real server does not interrupt unrelated established connections.
- Stopping or powering off the active director moves both VIPs within the approved interval.
- VRRP communication loss raises an alert and does not go unnoticed as two masters.
- Client-visible source, TLS behavior, session state, logging, and application transactions remain correct.
- Every persistent network, firewall, sysctl, and Keepalived change has an exact rollback.
Back up and capture the baseline
change_id="lvs-ha-20260824"
sudo install -d -m 0700 "/root/lvs-change-backup/${change_id}"

for path in /etc/keepalived/keepalived.conf \
            /etc/sysctl.d/60-lvs.conf \
            /etc/nftables.conf; do
  if sudo test -e "$path"; then
    sudo cp -a "$path" "/root/lvs-change-backup/${change_id}/"
  fi
done

ip -brief address
ip route show table all
sudo ss -lntup
sudo nft list ruleset
sudo ipvsadm -Ln --stats 2>/dev/null || true
systemctl status keepalived 2>/dev/null || true
Capture the same evidence on both directors and real servers. Store interface names, MAC addresses, routes, upstream gateway, firewall owner, MTU, reverse-path filter settings, ARP behavior, package versions, and existing cluster software. Do not assume both nodes are symmetrical because their intended configuration is symmetrical.
Install current packages without starting an empty service
# Debian and Ubuntu.
sudo apt update
sudo apt install keepalived ipvsadm

# RHEL, Rocky Linux and AlmaLinux.
sudo dnf install keepalived ipvsadm

# Prevent an unreviewed default configuration from becoming active.
sudo systemctl disable --now keepalived 2>/dev/null || true
Install from the supported distribution repositories unless the organization maintains a tested package pipeline. Do not install a fixed EL5-era RPM on a current host. Package names, default files, systemd units, SELinux policy, and compiled Keepalived features vary, so record the actual release.
keepalived --version
ipvsadm --version
systemctl cat keepalived
rpm -qi keepalived ipvsadm 2>/dev/null || \
  dpkg-query -W keepalived ipvsadm
Load and verify the IPVS kernel components
sudo modprobe ip_vs
sudo modprobe ip_vs_wlc
sudo modprobe nf_conntrack

lsmod | grep -E '^ip_vs|^nf_conntrack'
test -r /proc/net/ip_vs && sudo ipvsadm -Ln

# Persist only modules required by the selected scheduler and method.
printf '%s\n' ip_vs ip_vs_wlc nf_conntrack \
  | sudo tee /etc/modules-load.d/ipvs.conf >/dev/null
IPVS scheduling methods are kernel modules. Keepalived can request the configured scheduler, but a minimal or custom kernel may not provide it. Validate on both directors before advertising the VIP.
Enable forwarding and suppress redirects for NAT
# /etc/sysctl.d/60-lvs.conf
net.ipv4.ip_forward = 1
net.ipv4.conf.all.send_redirects = 0
net.ipv4.conf.default.send_redirects = 0
net.ipv4.conf.enp1s0.send_redirects = 0
net.ipv4.conf.enp2s0.send_redirects = 0
sudo sysctl --system
sysctl net.ipv4.ip_forward \
  net.ipv4.conf.all.send_redirects \
  net.ipv4.conf.enp1s0.send_redirects \
  net.ipv4.conf.enp2s0.send_redirects
These persistent settings replace one-time writes to /proc/sys/net/ipv4/*. Interface names must match the host. Reverse-path filtering needs a topology decision: strict mode may drop valid asymmetric or multi-homed traffic, while disabling it broadly weakens spoofing resistance. Test the actual routes and use the narrowest working value.
Permit VRRP, synchronization, health checks, and forwarding
VRRP is IP protocol 112, not a TCP or UDP port. With unicast peers, allow protocol 112 only between the director addresses on the selected interface. If IPVS connection synchronization is enabled, allow its configured multicast or unicast group, port, and interface. Health checks originate from a director address and must reach the real-server port.
# Illustrative nftables rules to merge into the owned ruleset.
ip protocol vrrp ip saddr { 192.0.2.11, 192.0.2.12 } accept

# Client virtual service.
ip daddr 192.0.2.100 tcp dport 443 accept

# Forward the approved client flow toward the real servers and its replies.
iifname "enp1s0" oifname "enp2s0" tcp dport 8443 accept
ct state established,related accept
Unsafe: flushing an existing nftables/iptables ruleset or installing a default drop remotely can remove SSH, cluster, DNS, monitoring, container, and return-path rules. Identify which tool owns the firewall, merge a bounded rule set, validate it with nft -c -f, use console access and a timed rollback, then test from every approved network.
Create a protected director-health script
sudo install -d -m 0755 /usr/local/libexec/keepalived
sudo install -m 0755 /dev/stdin \
  /usr/local/libexec/keepalived/check-ipvs <<'SCRIPT'
#!/bin/sh
test -r /proc/net/ip_vs || exit 1
/usr/sbin/ipvsadm -Ln >/dev/null 2>&1 || exit 1
exit 0
SCRIPT

sudo chown root:root /usr/local/libexec/keepalived/check-ipvs
sudo find /usr/local/libexec/keepalived -maxdepth 1 -type f -ls
This checks that the kernel IPVS interface can be read, not that every backend is healthy. Backend health belongs to each real_server checker. A director should not surrender the VIP merely because one real server fails. Store scripts in a root-owned directory that non-root users cannot modify, use absolute paths, bound execution time, and avoid network calls that can make both directors fail together.
Configure Director A with Keepalived
# /etc/keepalived/keepalived.conf on Director A
global_defs {
    router_id LVS_A
    script_user root
    enable_script_security
    lvs_sync_daemon enp2s0 VI_LVS id 1
}

vrrp_script check_ipvs {
    script "/usr/local/libexec/keepalived/check-ipvs"
    interval 2
    timeout 2
    fall 3
    rise 2
    weight 0
}

vrrp_instance VI_LVS {
    state BACKUP
    interface enp1s0
    virtual_router_id 51
    priority 150
    advert_int 1
    nopreempt

    unicast_src_ip 192.0.2.11
    unicast_peer {
        192.0.2.12
    }

    track_interface {
        enp2s0
    }
    track_script {
        check_ipvs
    }

    virtual_ipaddress {
        192.0.2.100/24 dev enp1s0
        198.51.100.1/24 dev enp2s0
    }
}

virtual_server 192.0.2.100 443 {
    delay_loop 5
    lvs_sched wlc
    lvs_method NAT
    protocol TCP
    quorum 1
    hysteresis 0

    real_server 198.51.100.21 8443 {
        weight 1
        inhibit_on_failure
        SSL_GET {
            url {
                path /healthz
                status_code 200
            }
            virtualhost service.example.test
            enable_sni
            connect_timeout 3
            retry 2
            delay_before_retry 2
        }
    }

    real_server 198.51.100.22 8443 {
        weight 1
        inhibit_on_failure
        SSL_GET {
            url {
                path /healthz
                status_code 200
            }
            virtualhost service.example.test
            enable_sni
            connect_timeout 3
            retry 2
            delay_before_retry 2
        }
    }
}
Both nodes start in BACKUP state so nopreempt can prevent an automatic failback when the higher-priority node returns. Director A wins the initial election through priority 150. The VRRP ID must match between peers and be unique on the Layer 2 domain. Unicast is useful where multicast is unavailable, but it does not encrypt or strongly authenticate the relationship; protect the network and firewall it precisely.
inhibit_on_failure implements the useful quiescent behavior: Keepalived leaves the real server in IPVS with weight zero rather than deleting its entry. No new connections select it, while state and visibility remain easier to reason about.
Configure Director B with only node-specific differences
# Director B differences. The virtual_server blocks remain identical.
global_defs {
    router_id LVS_B
    script_user root
    enable_script_security
    lvs_sync_daemon enp2s0 VI_LVS id 1
}

vrrp_instance VI_LVS {
    state BACKUP
    interface enp1s0
    virtual_router_id 51
    priority 100
    advert_int 1
    nopreempt

    unicast_src_ip 192.0.2.12
    unicast_peer {
        192.0.2.11
    }

    # Keep the same track_interface, track_script and both VIPs.
}
Generate both files from one reviewed template so only router ID, source address, peer address, and priority differ. Configuration drift between directors can remain hidden until failover. Compare hashes after accounting for the intended node variables.
Validate before enabling either director
sudo keepalived -t -f /etc/keepalived/keepalived.conf
sudo systemd-analyze verify keepalived.service
sudo /usr/local/libexec/keepalived/check-ipvs

# Confirm addresses are not already owned before first activation.
ip neigh show | grep -E '192\.0\.2\.100|198\.51\.100\.1' || true
sudo arping -D -I enp1s0 -c 3 192.0.2.100
sudo arping -D -I enp2s0 -c 3 198.51.100.1
Unsafe: starting both nodes before duplicate-address detection, VRRP firewall validation, and real-server return routing can create an address conflict or blackhole. Start the lower-priority node first, observe BACKUP, then start the preferred node and verify a single MASTER.
sudo systemctl enable --now keepalived
journalctl -u keepalived -n 100 --no-pager
ip -brief address show enp1s0
ip -brief address show enp2s0
sudo ipvsadm -Ln
Configure NAT return routing on each real server
The application listens on TCP 8443 at each real-server address. The real server sees the original client source, so its response route for that client must use 198.51.100.1, the backend gateway VIP on the active director. Health checks also need an allowed path from both director backend addresses.
ip -brief address
ip route
ip route get 203.0.113.10
sudo ss -lntp | grep ':8443'

# Temporary lab-only route test from console.
sudo ip route replace default via 198.51.100.1 dev enp1s0
ip route get 203.0.113.10
Unsafe: replacing or deleting a default route over the same remote connection can immediately disconnect the server, monitoring, package repositories, storage, and control plane. Use console access, capture every route and policy rule, add a more-specific test route first, then configure the approved persistent route through NetworkManager, netplan, systemd-networkd, or the platform network manager. Do not use broad route del -net commands copied from another topology.
Understand scheduler and weight choices
| Scheduler | Behavior | Use carefully when |
|---|---|---|
rr | Round robin across available real servers | Servers and connection costs are reasonably similar. |
wrr | Weighted round robin; higher weight receives a larger share | Weights represent measured capacity, not guesswork. |
lc | Chooses the server with fewer active connections | Connection count approximates work. |
wlc | Least connections adjusted by weight | Long-lived connections and unequal capacity coexist. |
sh or mh | Hash-oriented mapping intended to improve affinity characteristics | Backend membership changes and hashing flags are tested. |
sed or nq | Delay-oriented selection approaches | The workload and kernel implementation justify them. |
Weighted round robin is the correct expansion of wrr. It is not “waited round robin.” Observe active/inactive connections, request latency, CPU, queue depth, application saturation, and backend errors before changing weights.
Use persistence only for a demonstrated requirement
virtual_server 192.0.2.100 443 {
    persistence_timeout 600
    persistence_granularity 255.255.255.255
    # Other scheduler, method, protocol and real_server settings...
}
IPVS persistence keeps matching traffic mapped to the same real server for the persistence window. It does not refresh an established TCP connection and it does not replicate application session data. Source-based persistence can concentrate many users behind corporate NAT, carrier-grade NAT, or proxies onto one backend. Prefer stateless applications, shared session stores, or application-aware affinity when possible.
Make health checks reflect ability to serve
| Checker | What it proves | What it can miss |
|---|---|---|
TCP_CHECK | A TCP connection can be established | Wrong content, read-only failure, dependency failure, TLS name/certificate, or stuck worker |
HTTP_GET | Expected HTTP path and response behavior | TLS-specific failures and business operations outside the endpoint |
SSL_GET | TLS connection plus expected HTTP path/response | All user workflows and every downstream dependency |
MISC_CHECK | An organization-defined bounded command succeeds | Anything the script omits; a bad script can block or flap checks |
SMTP_CHECK or DNS_CHECK | Protocol-specific exchange reaches a valid point | End-to-end delivery, data correctness, or all query types |
A health endpoint should prove that this node can accept the intended class of request. Do not make every backend fail because one shared optional dependency is unavailable. Use fall, rise, retries, delay, and hysteresis to avoid flapping, but do not hide a sustained failure with excessively long thresholds.
Drain a real server for maintenance
# Set one real server's weight to zero for new connections.
sudo ipvsadm -e -t 192.0.2.100:443 \
  -r 198.51.100.21:8443 -m -w 0

watch -n 1 'sudo ipvsadm -Ln --stats; sudo ipvsadm -Ln --rate'

# Restore the configured weight after maintenance.
sudo ipvsadm -e -t 192.0.2.100:443 \
  -r 198.51.100.21:8443 -m -w 1
A manual ipvsadm edit is temporary because Keepalived remains the configuration owner and may overwrite it. Use an approved maintenance mechanism, temporarily disable or adjust the checker, or update the managed configuration. Wait for active connections and application work to drain according to protocol behavior.
Load balance MySQL only with database-role awareness
virtual_server 192.0.2.100 3306 {
    delay_loop 10
    lvs_sched wlc
    lvs_method NAT
    protocol TCP

    real_server 198.51.100.21 3306 {
        weight 1
        inhibit_on_failure
        TCP_CHECK {
            connect_timeout 3
            retry 2
            delay_before_retry 2
        }
    }
}
A TCP check proves that MySQL accepts a connection, not that the node has the correct replication role, is writable, is within an acceptable replication delay, or contains current data. A write VIP normally needs exactly one authorized writer and a role-aware check. A read pool needs lag and consistency policy. Use a bounded MISC_CHECK only when its client credentials are stored in a root-readable file and its query cannot alter data.
# /etc/keepalived/mysql-health.cnf, mode 0600
[client]
user=loadbalancer_health
password=replace-with-managed-secret
connect_timeout=2
Unsafe: placing a database password directly in a world-readable Keepalived or ldirectord configuration, process argument, shell history, or monitoring output exposes a reusable credential. Use the minimum database privilege, a source restriction, a protected client file or secret delivery mechanism, rotation, and audit logging.
Configure Direct Routing when it matches the network
For Direct Routing, change the virtual service to lvs_method DR. The director and real servers must satisfy the required Layer 2 reachability. Each real server owns the service VIP locally but must not answer ARP for it on the service network. It then replies directly to clients.
# /etc/sysctl.d/60-lvs-dr.conf on each real server
net.ipv4.conf.all.arp_ignore = 1
net.ipv4.conf.all.arp_announce = 2
net.ipv4.conf.default.arp_ignore = 1
net.ipv4.conf.default.arp_announce = 2
net.ipv4.conf.enp1s0.arp_ignore = 1
net.ipv4.conf.enp1s0.arp_announce = 2
sudo sysctl --system
sudo ip address add 192.0.2.100/32 dev lo
ip address show dev lo
ip route get 203.0.113.10

# Verify the real server does not claim the VIP on the service LAN.
sudo arping -I enp1s0 -c 3 192.0.2.100
Persist the VIP through the distribution network manager and test boot behavior. The service must accept connections addressed to the VIP. Firewalls and reverse-path validation must permit the asymmetric request/response design.
Unsafe: adding the VIP to real servers before ARP suppression can make a real server answer for the service address and bypass the director. Apply and verify ARP policy first in an isolated test, add one backend, validate from multiple network points, then expand.
Synchronize IPVS connection state when continuity requires it
The lvs_sync_daemon directive ties the IPVS synchronization role to VI_LVS: the MASTER runs the master sync daemon and a non-master runs the backup daemon. The peer can then receive IPVS connection state. Synchronization helps existing flows after director failure, but it does not synchronize application memory, TLS termination outside IPVS, firewall state unrelated to IPVS, or real-server session storage.
sudo ipvsadm -Ln --stats
sudo ipvsadm -Lc
cat /proc/net/ip_vs_sync 2>/dev/null || true
journalctl -u keepalived | grep -i sync

# Observe the configured sync network and VRRP without exposing payloads.
sudo tcpdump -ni enp2s0 'ip proto 112 or udp port 8848'
Confirm the actual sync group, port, interface, MTU, kernel support, and firewall rule from the deployed Keepalived configuration. Test long-lived connections through an ungraceful director failure. A synchronized entry can still fail if upstream neighbor state, routes, or the application path are wrong.
Prevent silent split brain
VRRP peers can both become MASTER when each stops receiving the other's advertisements while each still reaches clients. Unicast reduces multicast dependencies but does not eliminate partition risk. Monitor VRRP state, duplicate VIP ownership, gratuitous ARP changes, peer reachability, interface state, and upstream MAC observations.
| Condition | Required behavior | Evidence |
|---|---|---|
| Director process stops | Peer owns both VIPs and serves new traffic | VRRP transition log, addresses, ARP/neighbor update, client transaction |
| Frontend interface fails | Faulted node releases ownership; peer takes over | Tracked-interface state and upstream observation |
| Backend interface fails | Node cannot retain VIP while unable to forward | Track state, both VIPs, client test and real-server traffic |
| VRRP traffic blocked one way | Alert immediately; duplicate-master risk is visible | Packet capture from both nodes and duplicate-address monitor |
| Preferred node returns | Current healthy owner remains MASTER with nopreempt | No unnecessary second failover |
Keepalived VRRP is appropriate when the primary resource is a floating address and IPVS state. If the service requires storage ownership, strict resource ordering, quorum decisions, and fencing, use a cluster resource manager such as Pacemaker with Corosync and tested STONITH rather than treating VRRP as a database-cluster consensus system.
Operate an existing ldirectord deployment safely
ldirectord monitors real servers and updates IPVS. Its global controls remain useful: checktimeout, checkinterval, configuration autoreload, logging, and quiescent=yes. Package availability differs by current distribution. A MySQL negotiate check may require Perl DBI and the MySQL DBD driver; a connection-only check does not prove query or role health.
# /etc/ha.d/ldirectord.cf
checktimeout=10
checkinterval=5
autoreload=yes
logfile="/var/log/ldirectord.log"
quiescent=yes

virtual=192.0.2.100:3306
    real=198.51.100.21:3306 masq
    real=198.51.100.22:3306 masq
    service=mysql
    scheduler=wrr
    protocol=tcp
    checktype=negotiate
    login="loadbalancer_health"
    passwd="replace-with-managed-secret"
    database="health"
    request="SELECT 1"
sudo install -m 0600 /path/to/reviewed/ldirectord.cf \
  /etc/ha.d/ldirectord.cf
sudo touch /var/log/ldirectord.log
sudo chown root:root /var/log/ldirectord.log
sudo chmod 0600 /var/log/ldirectord.log

# Foreground debug during an approved test window.
sudo ldirectord -d -n /etc/ha.d/ldirectord.cf

sudo ipvsadm -Ln
sudo ipvsadm -Ln --stats
Do not run Keepalived and ldirectord as competing owners of the same virtual service. Select one IPVS configuration owner, document it, and prevent the other from overwriting weights or entries.
Operate Heartbeat-managed VIPs only with an upgrade plan
Some maintained environments still use Linux-HA Heartbeat files under /etc/ha.d. The following describes their roles so the service can be audited and recovered. For a new LVS deployment, Keepalived directly combines VRRP, IPVS programming, and health checks with fewer moving parts.
# /etc/ha.d/ha.cf on both nodes
keepalive 1
deadtime 10
warntime 5
initdead 60
ucast enp3s0 10.0.0.12
node lb1.example.test
node lb2.example.test
use_logd yes
auto_failback no
On the second node, the unicast peer is 10.0.0.11. keepalive controls heartbeat frequency, deadtime controls failure declaration, warntime reports late heartbeats, and initdead allows the network to become usable after boot. These timers need failure testing under real latency and load.
# /etc/ha.d/authkeys, identical on both nodes and mode 0600
auth 1
1 sha1 replace-with-long-random-secret

# /etc/ha.d/haresources, identical on both nodes
lb1.example.test IPaddr::192.0.2.100/24/enp1s0 ldirectord::ldirectord.cf
sudo chown root:root /etc/ha.d/authkeys
sudo chmod 0600 /etc/ha.d/authkeys
sudo sha256sum /etc/ha.d/ha.cf /etc/ha.d/authkeys /etc/ha.d/haresources
Unsafe: Heartbeat authentication options such as CRC, MD5, or SHA-1 do not provide modern peer security. Never use CRC as authentication, never publish the shared secret, and do not expose the heartbeat path to untrusted networks. Isolate and firewall the channel, monitor it, and plan migration to a currently supported HA design. Heartbeat without fencing is not safe coordination for shared writable storage.
Observe the data plane and control plane separately
# Control plane.
ip -brief address
journalctl -u keepalived --since '30 minutes ago'
sudo tcpdump -ni enp1s0 'ip proto 112'

# IPVS data plane.
sudo ipvsadm -Ln
sudo ipvsadm -Ln --stats
sudo ipvsadm -Ln --rate
sudo ipvsadm -Lc

# Routing and packet evidence.
ip route get 203.0.113.10
sudo tcpdump -ni any 'host 198.51.100.21 and tcp port 8443'
| Metric | Question | Alert example |
|---|---|---|
| VRRP state and transitions | Who owns the VIP and why did it change? | Two masters, no master, or frequent transitions |
| Healthy real-server weight | Which nodes are eligible for new flows? | Quorum lost or one server repeatedly flaps |
| Connections, packets and bytes | Does distribution match scheduler and capacity? | One server receives unexpected concentration |
| Connection rate and inactive count | Is traffic changing or state accumulating? | Rate spike, timeout mismatch, or growing inactive state |
| Health-check latency and failures | Is failure application-specific or network-wide? | Both directors fail checks simultaneously |
| Client transaction | Does the complete service work? | VIP accepts TCP but application result is wrong |
Unsafe: packet captures and connection tables can contain client addresses and sensitive traffic metadata. Limit filters and duration, write to a protected path, control access, and delete or archive according to the incident-retention policy.
Run a failure test matrix
| Test | Expected result | Do not accept |
|---|---|---|
| Stop application on real server 1 | Its weight becomes zero after the configured fall threshold; server 2 continues | VIP failover or both servers removed by a shared weak check |
| Restore real server 1 | It returns after the rise threshold and receives new traffic | Immediate flapping or full traffic before warm readiness |
| Stop Keepalived on MASTER | Peer takes both VIPs; new client transactions pass | Public VIP and backend gateway split across nodes |
| Power off MASTER | Unannounced failure still converges within objective | Success only for graceful service stop |
| Disconnect frontend | Tracked failure releases ownership | Node retains backend gateway while public path is unusable |
| Disconnect backend | Tracked failure releases both VIPs | VIP remains on a node unable to forward |
| Block VRRP one direction | Split-brain alert fires with packet evidence | Silent double MASTER |
| All real servers fail | Quorum alert and intentional client behavior | A local sorry server that returns HTTP 200 and hides outage |
| Long-lived connection during failover | Observed result matches the documented synchronization objective | Claimed seamless state without a real test |
| Preferred node returns | No automatic failback with nopreempt | Second avoidable interruption |
Troubleshoot by symptom
| Symptom | Likely boundary | Evidence |
|---|---|---|
| VIP is absent on both nodes | Keepalived syntax, FAULT state, tracked interface/script, duplicate address | Config test, journal, addresses, script exit |
| VIP is present on both nodes | VRRP protocol blocked, peer/source mismatch, VRID collision, network partition | Packet capture on both nodes and VRRP logs |
| VIP accepts no connections | Firewall, IPVS service absent, local bind conflict, upstream neighbor state | ipvsadm -Ln, nft trace/counters, socket list, ARP/ND |
| Real server sees SYN but client times out | NAT return gateway, policy route, firewall, reverse-path filtering | Simultaneous captures and ip route get with source |
| One backend never receives traffic | Weight zero, health failure, scheduler/persistence, route or application | IPVS weights/stats and checker log |
| Health check passes but application fails | Check is too shallow or uses a different name/path/source | Replay exact client transaction from director and client |
| Failover works only after ARP cache expiry | Gratuitous ARP, switch security, VMAC, upstream behavior | Neighbor/MAC table and failover packet capture |
| Connections reset on failover | Sync not running, state not transferred, timeout mismatch, non-IPVS state | Sync traffic, ipvsadm -Lc, firewall and application state |
Perform planned maintenance without surprise failback
- Confirm the peer is healthy, synchronized, configured identically, and able to reach all real servers.
- Pause deployment changes and capture IPVS, VRRP, routing, firewall, and client baselines.
- Move the VIP through the approved method or stop Keepalived on the active node.
- Verify both VIPs moved together and client transactions pass through the peer.
- Patch or maintain the inactive director, reboot if required, and verify it returns as BACKUP.
- Because
nopreemptis configured, leave the healthy current MASTER in place unless a controlled move is required. - Repeat for the other node and attach evidence to the change.
Roll back one layer at a time
change_id="lvs-ha-20260824"

sudo systemctl stop keepalived
sudo install -m 0644 \
  "/root/lvs-change-backup/${change_id}/keepalived.conf" \
  /etc/keepalived/keepalived.conf
sudo keepalived -t -f /etc/keepalived/keepalived.conf
sudo systemctl start keepalived

# Verify ownership, IPVS topology, routing and application transaction.
ip -brief address
sudo ipvsadm -Ln
journalctl -u keepalived -n 100 --no-pager
Unsafe: flushing IPVS, deleting both VIPs, restoring an entire network directory, flushing the firewall, or rebooting both directors is not a controlled rollback. Identify whether the failure belongs to VRRP, IPVS, health checks, routing, firewall, sysctl, or the application. Restore the exact owning configuration and keep one working service path available.
Production completion checklist
- The chosen NAT, DR, or TUN method and complete request/response path are documented.
- Frontend, backend, peer, health-check, synchronization, and management networks have explicit firewall ownership.
- Both directors use the same supported package versions, kernel modules, virtual services, real servers, scheduler, weights, checks, and timeouts.
- Only node identity, unicast source/peer, and priority differ in the reviewed Keepalived template.
- Both the public VIP and NAT backend gateway VIP always move together.
- Real-server routing is persistent and verified from the actual client source path.
- Health checks test service readiness without creating a shared failure dependency.
- Persistence is enabled only for an explicit session requirement and tested with NAT/proxy client populations.
- IPVS connection synchronization is either tested end to end or continuity is documented as new-connections only.
- Backend, interface, process, power, VRRP partition, total pool, return-route, and recovery tests pass.
- Monitoring can detect two masters, no master, quorum loss, backend flapping, skewed distribution, and failed client transactions.
- Backups and precise rollback commands exist for Keepalived, firewall, sysctl, routes, and real-server VIP settings.